SMYRF: Efficient Attention using Asymmetric Clustering
NeurIPS 2020
We propose a novel type of balanced clustering algorithm to approximate attention. Attention complexity is reduced from O(N^2) to O(NlogN), where N is the sequence length. Our algorithm, SMYRF, uses Locality Sensitive Hashing (LSH) in a novel way by defining new Asymmetric transformations and an adaptive scheme that produces balanced clusters. The biggest advantage of SMYRF is that it can be used as a drop-in replacement for dense attention layers without any retraining. On the contrary, prior fast attention methods impose constraints (e.g. queries and keys share the same vector representations) and require re-training from scratch. We apply our method to pre-trained state-of-the-art Natural Language Processing and Computer Vision models and we report significant memory and speed benefits. Notably, SMYRF-BERT outperforms (slightly) BERT on GLUE, while using 50% less memory. We also show that SMYRF can be used interchangeably with dense attention before and after training. Finally, we use SMYRF to train GANs with attention in high resolutions. Using a single TPU, we were able to scale attention to 128x128=16k and 256x256=65k tokens on BigGAN on CelebA-HQ.
Results
Memory-quality trade-off
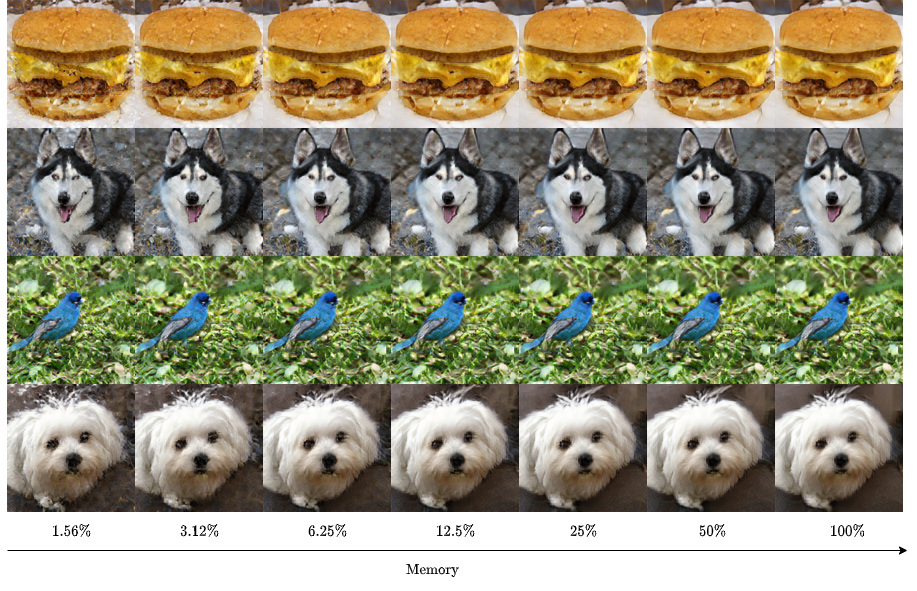
GLUE benchmark
| Avg. | # | C | CoLA | MNLI-m/mm | MRPC | QNLI | QQP | RTE | SST-2 | STS-B | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| BERT128 | 82.69 | 1 | 1 | 57.83 | 84.43/84.68 | 88.41 | 91.31 | 89.70 | 65.70 | 93.46 | 88.73 |
| SMYRF-BERT2x32 | </td>82.98 | 2 | 32 | 58.79 | 83.76/84.27 | 87.69 | 91.14 | 89.72 | 68.59 | 93.23 | 89.65 |
| SMYRF-BERT2x16 | </td>81.74 | 2 | 16 | 58.90 | 82.86/83.49 | 85.72 | 89.53 | 89.33 | 64.98 | 93.12 | 87.75 |
| BERT64 | 81.57 | 1 | 64 | 58.80 | 82.34/82.47 | 87.02 | 90.48 | 89.69 | 61.73 | 93.00 | 88.64 |
| BERT32 | 73.56 | 1 | 32 | 56.40 | 64.51/63.41 | 77.89 | 79.81 | 88.59 | 55.23 | 92.66 | 83.53 |
Interchangeability of SMYRF and dense attention
Results on IMDB dataset. Using dense attention on inference consistently improves results, nearly matching dense attention perf.
| Memory | SMYRF Inference | Accuracy | |
|---|---|---|---|
| RoBERTa | 100% | ☒ | 94.96% |
| SMYRF-RoBERTa | 50% | ☒ | 93.72% |
| SMYRF-RoBERTa | 50% | ☑ | 94.62% |
| BERT | 100% | ☒ | 94.12% |
| SMYRF-BERT | 50% | ☒ | 92.64% |
| SMYRF-BERT | 50% | ☑ | 93.54% |
Smyrf-BigGAN training on Celeba-HQ-128
Generated faces by a Smyrf-BigGAN trained on 128x128 resolution with attention at 128x128, using 50% of dense memory. 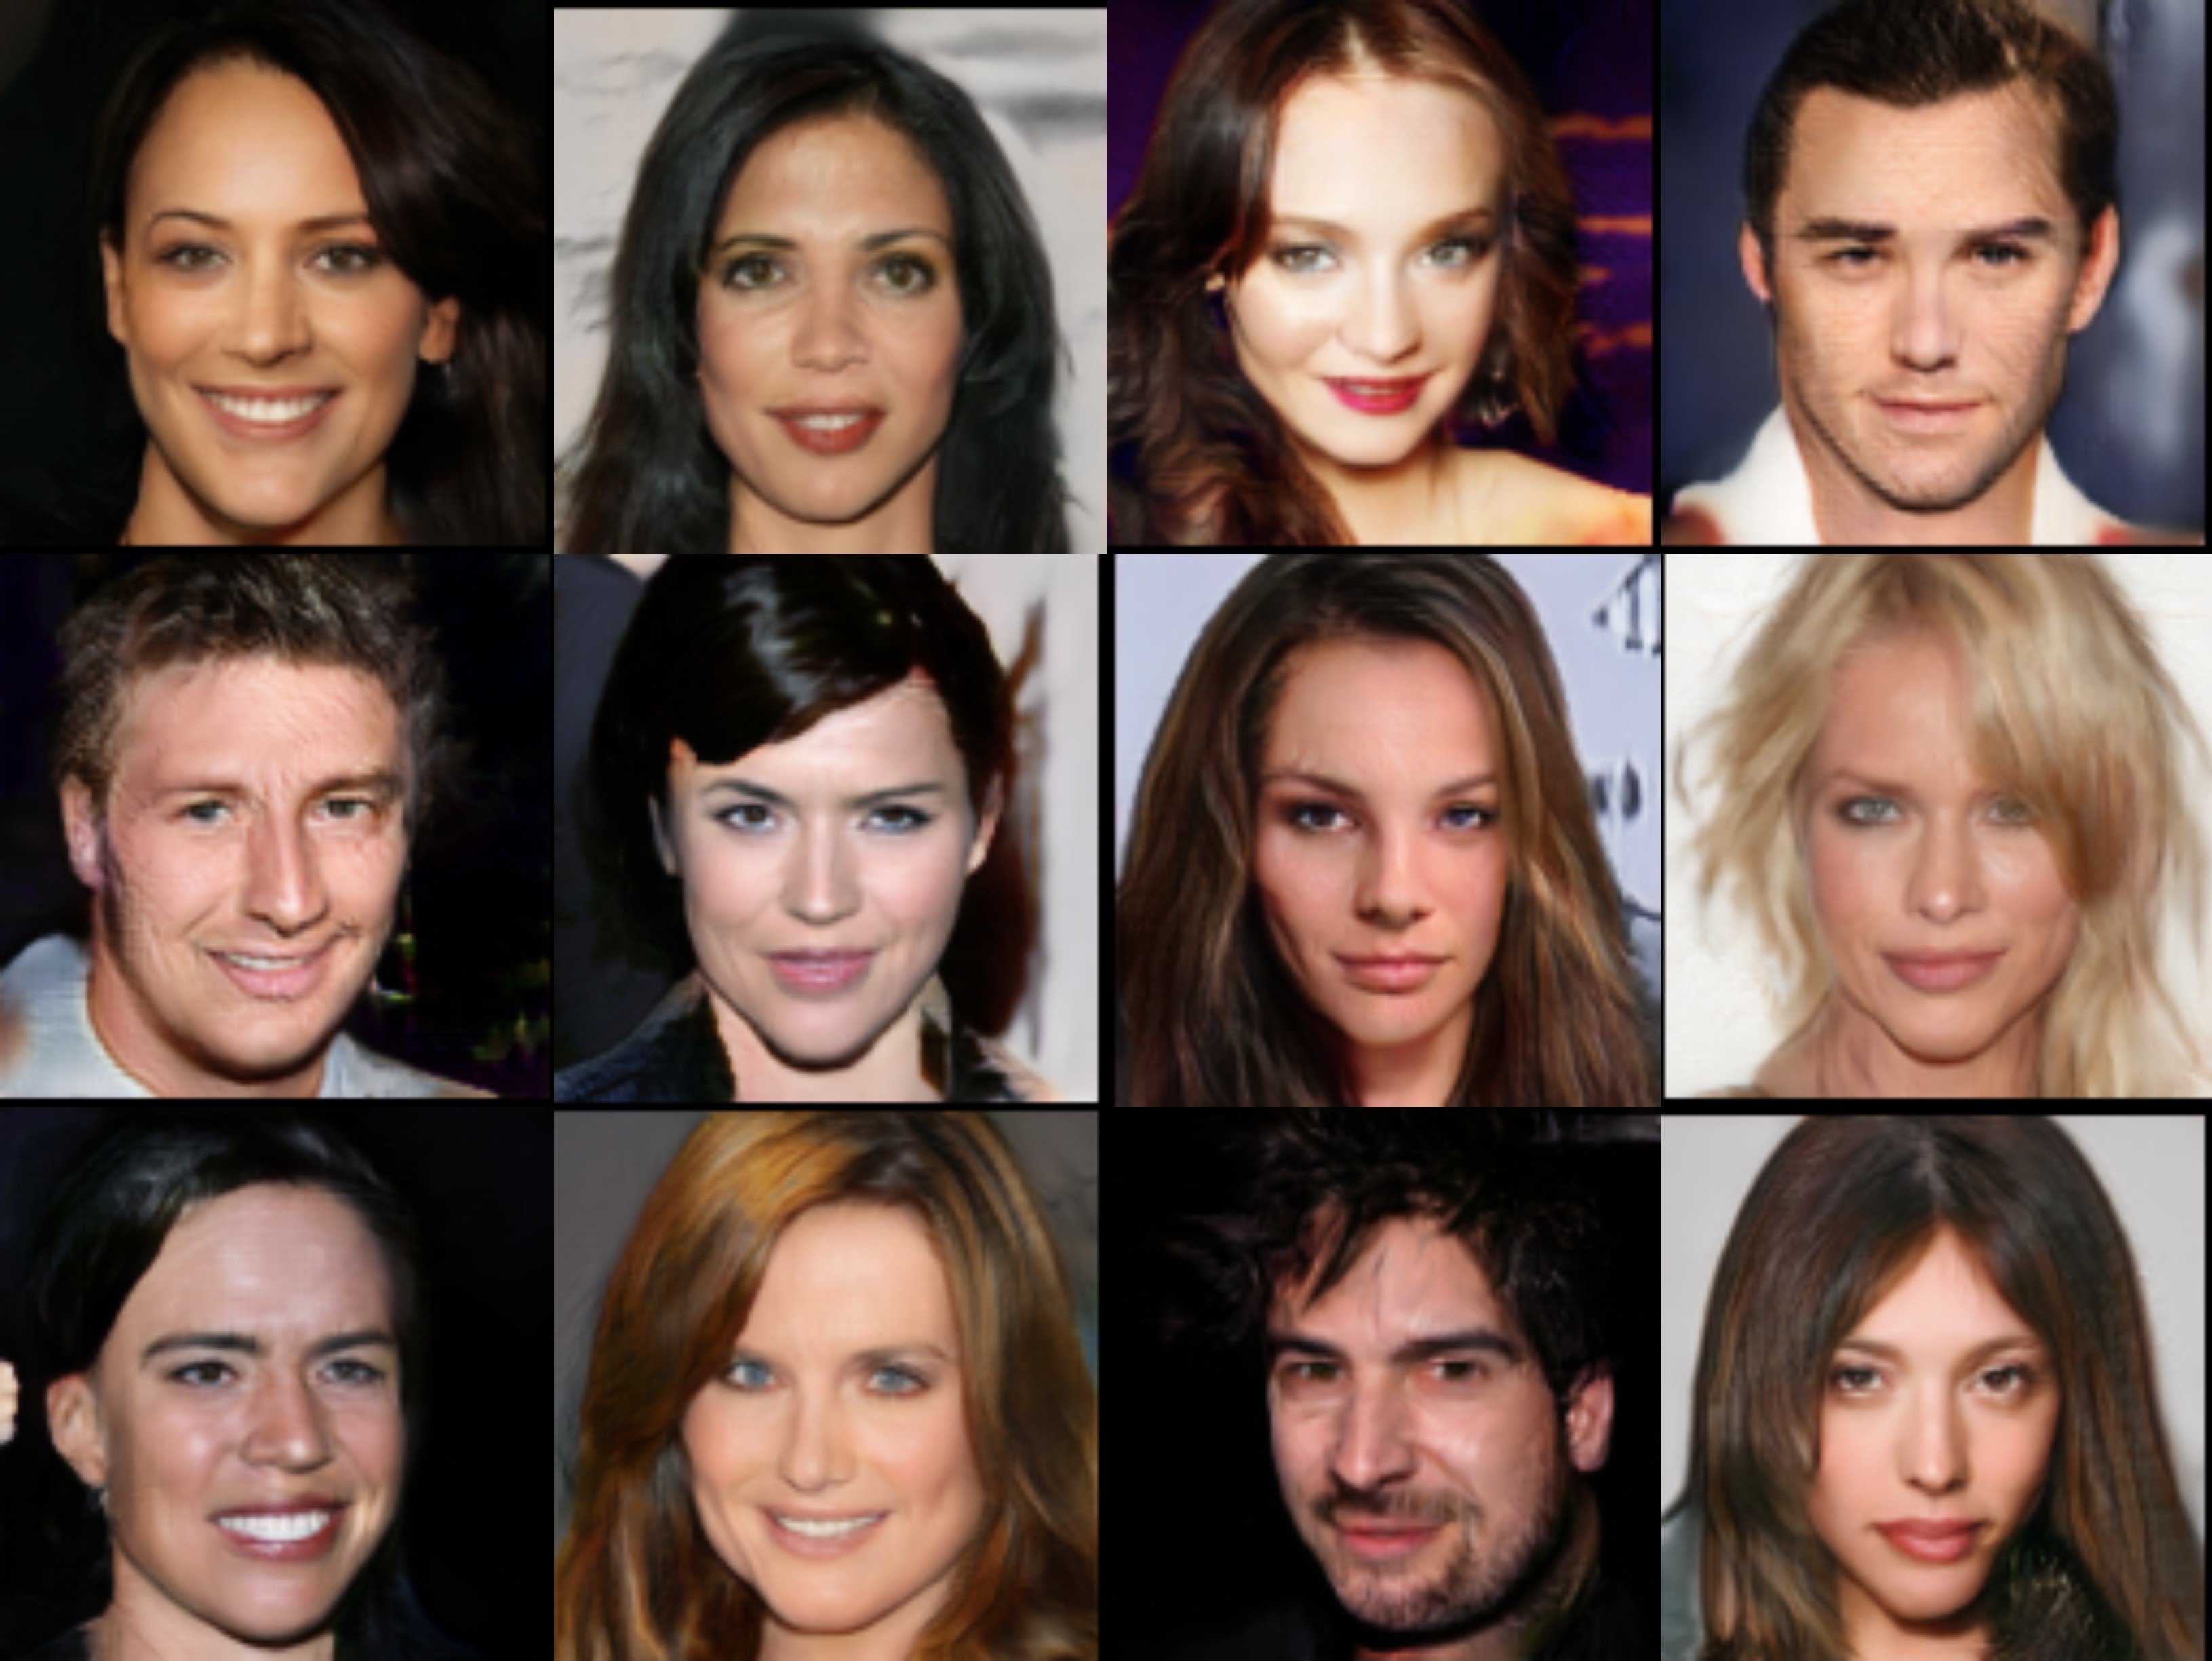
Results after 120k iterations:
| Resolution | Attention | # | C | FID | |
|---|---|---|---|---|---|
| BigGAN | 128x128 | 64x64 | 1 | 4096 | 26.06 |
| Smyrf-BigGAN | 128x128 | 128x128 | 4 | 2048 | 25.03 |
where # denotes number of hashes and C number of queries per cluster.